|
Miso Lee I am a Ph.D. student in Visual Computing Lab at Sungkyunkwan University (SKKU), advised by Prof. Jae-Pil Heo. My research interests span computer vision and deep learning, especially 3D vision and camera pose estimation. I was a research intern at NAVER Cloud in the summer of 2026, working on 4D human-scene reconstruction. |
|
Publications |
|
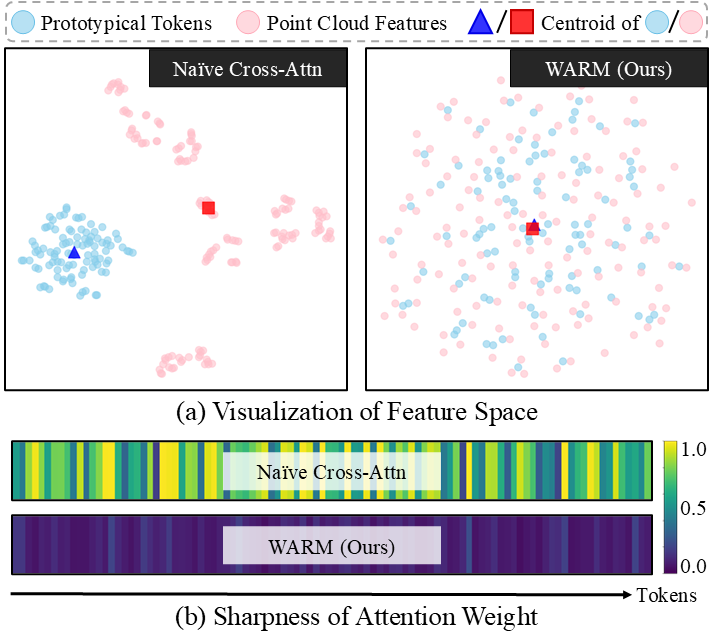
White Aggregation and Restoration for Few-shot 3D Point Cloud Semantic Segmentation
Jiyun Im, SuBeen Lee, Miso Lee, and Jae-Pil Heo European Conference on Computer Vision (ECCV), 2026 code / arXiv |
|
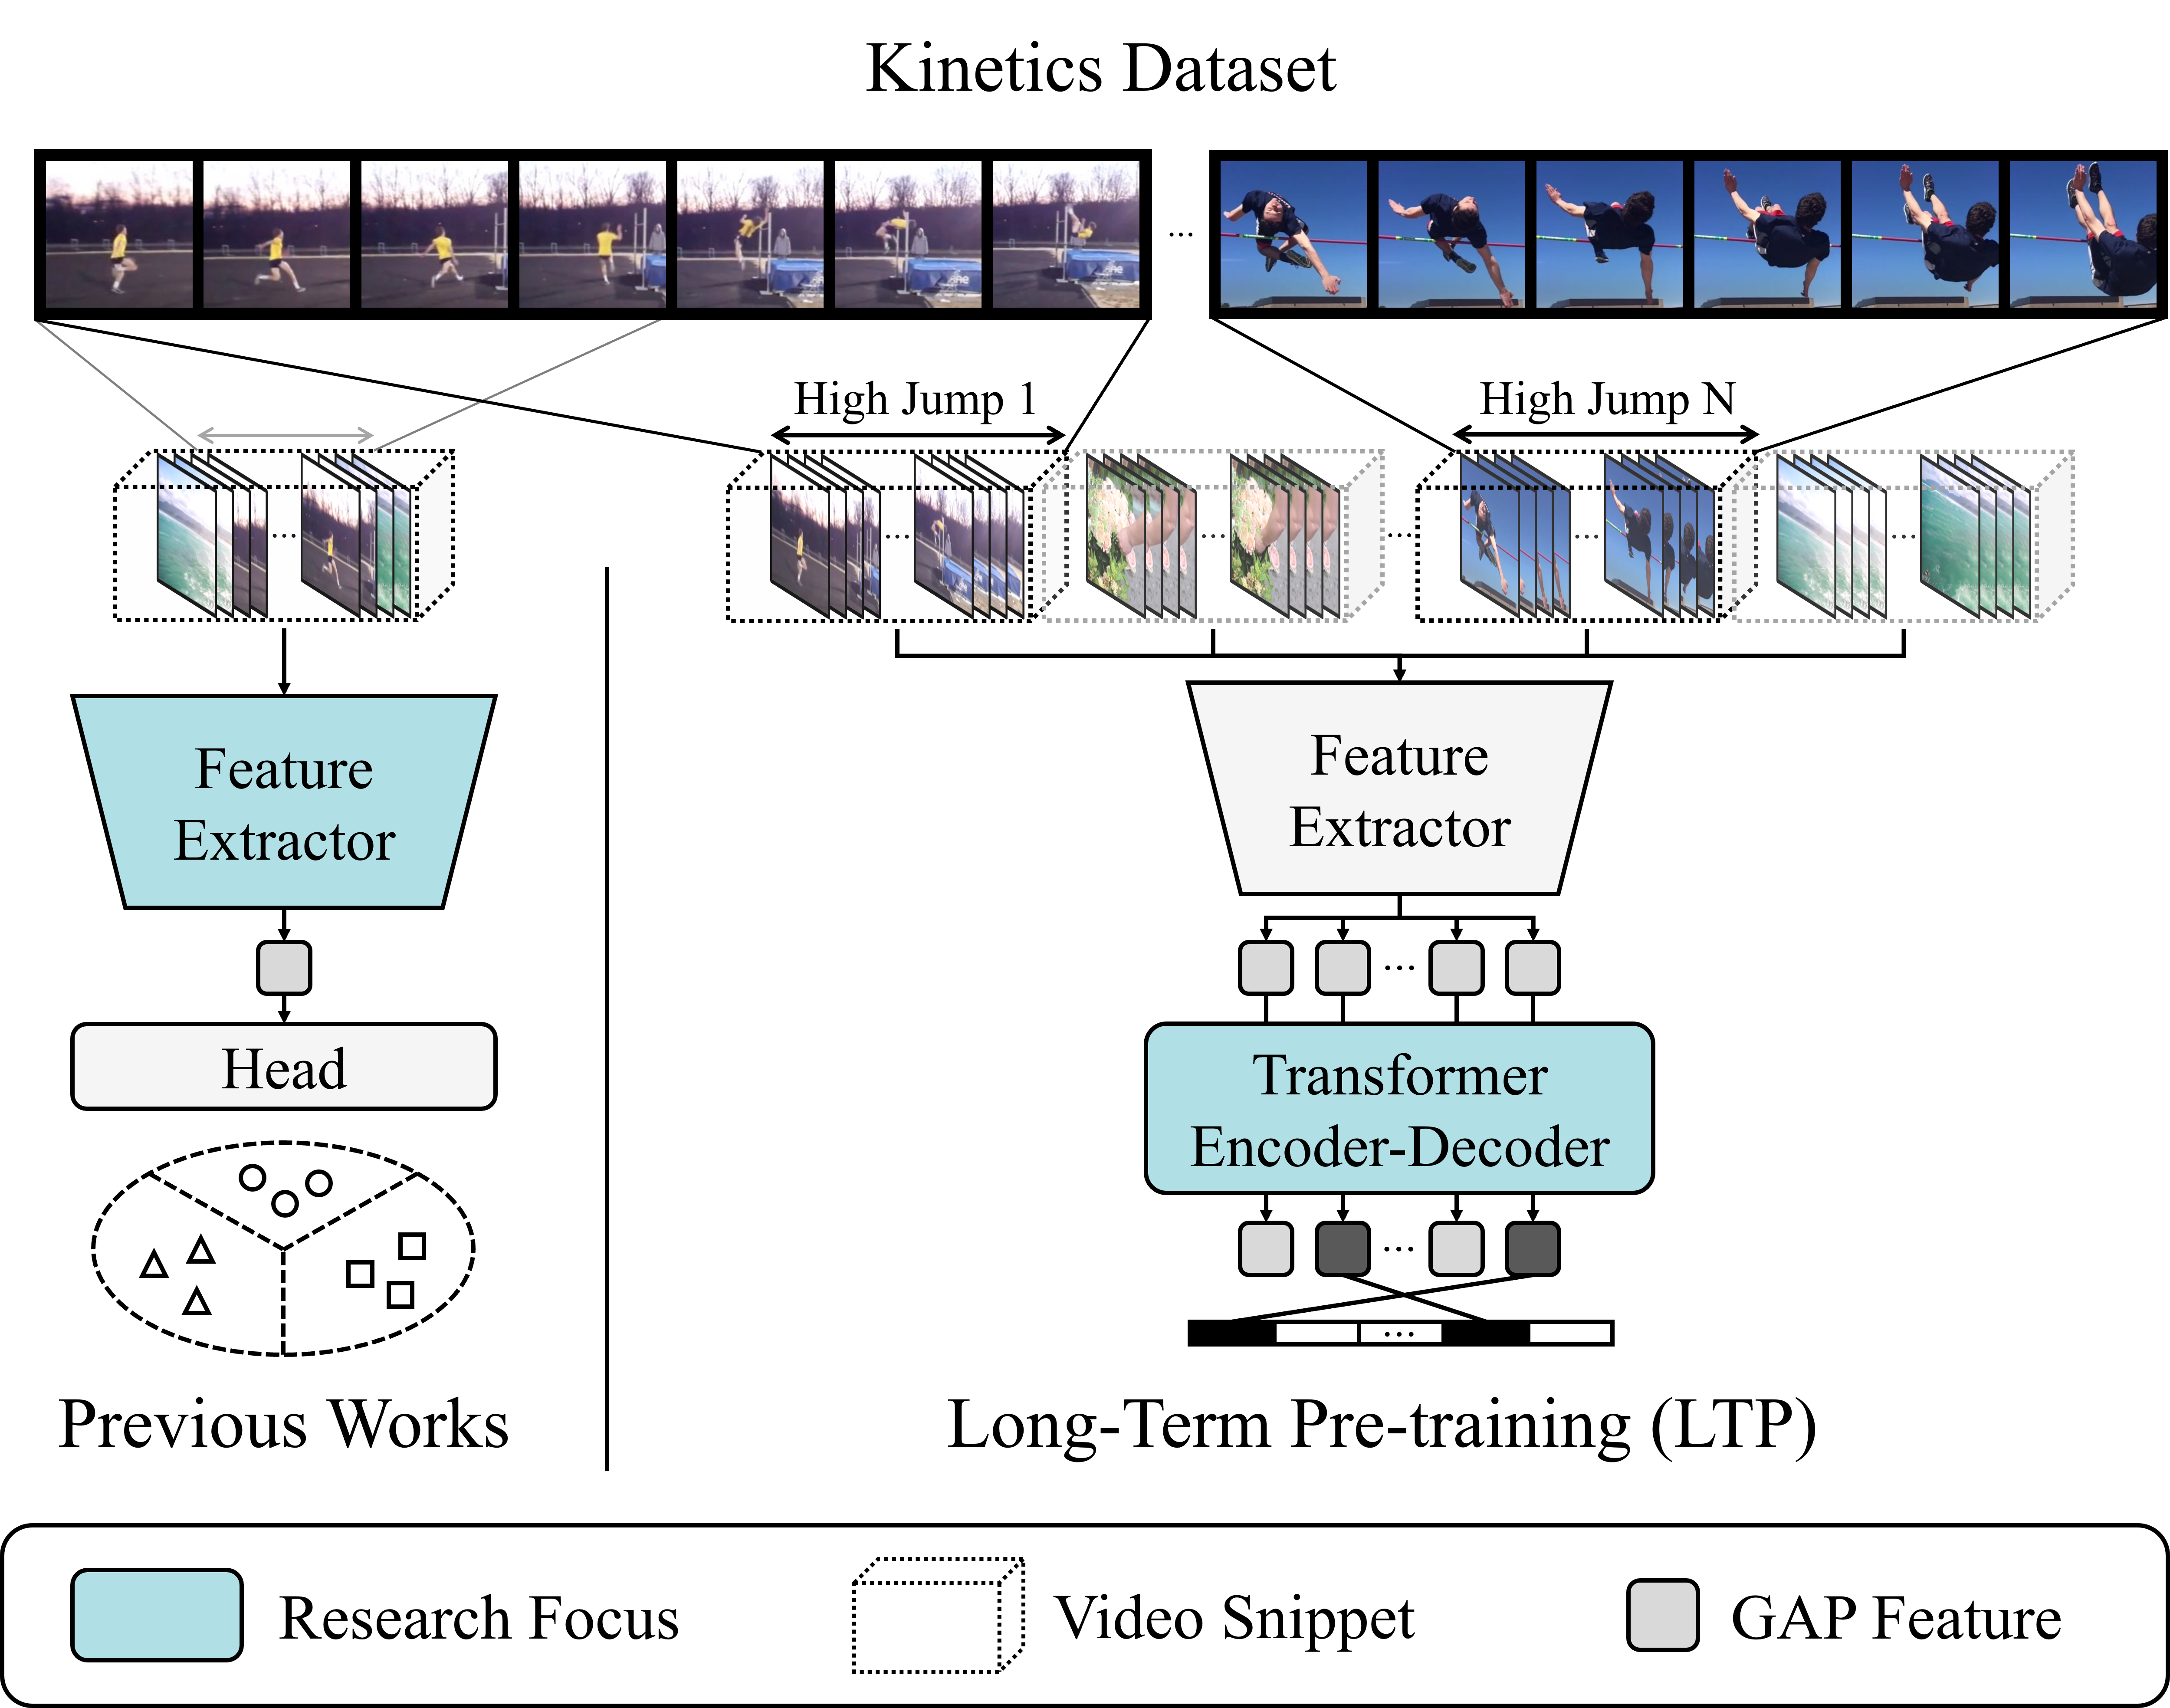
Long-term Pre-training for Temporal Action Detection with Transformers
Jihwan Kim, Miso Lee, and Jae-Pil Heo Pattern Recognition, 2026 paper / arXiv |
|
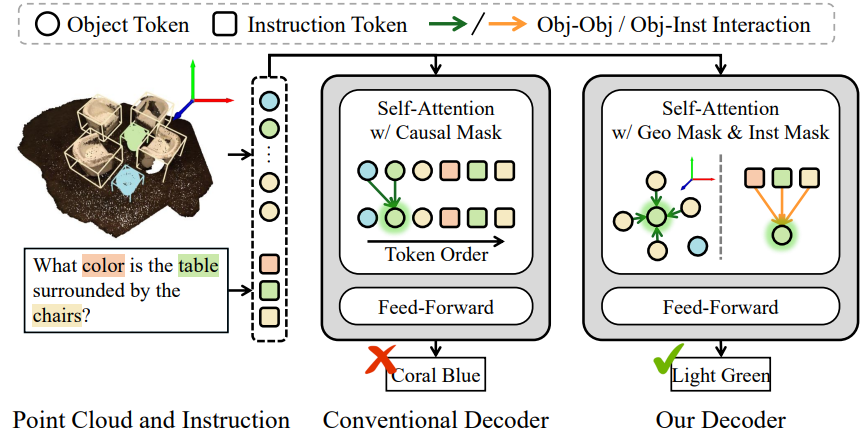
Masking Matters: Unlocking the Spatial Reasoning Capabilities of LLMs for 3D Scene-Language Understanding
Yerim Jeon, Miso Lee, WonJun Moon, and Jae-Pil Heo IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026 code / paper / arXiv |
|
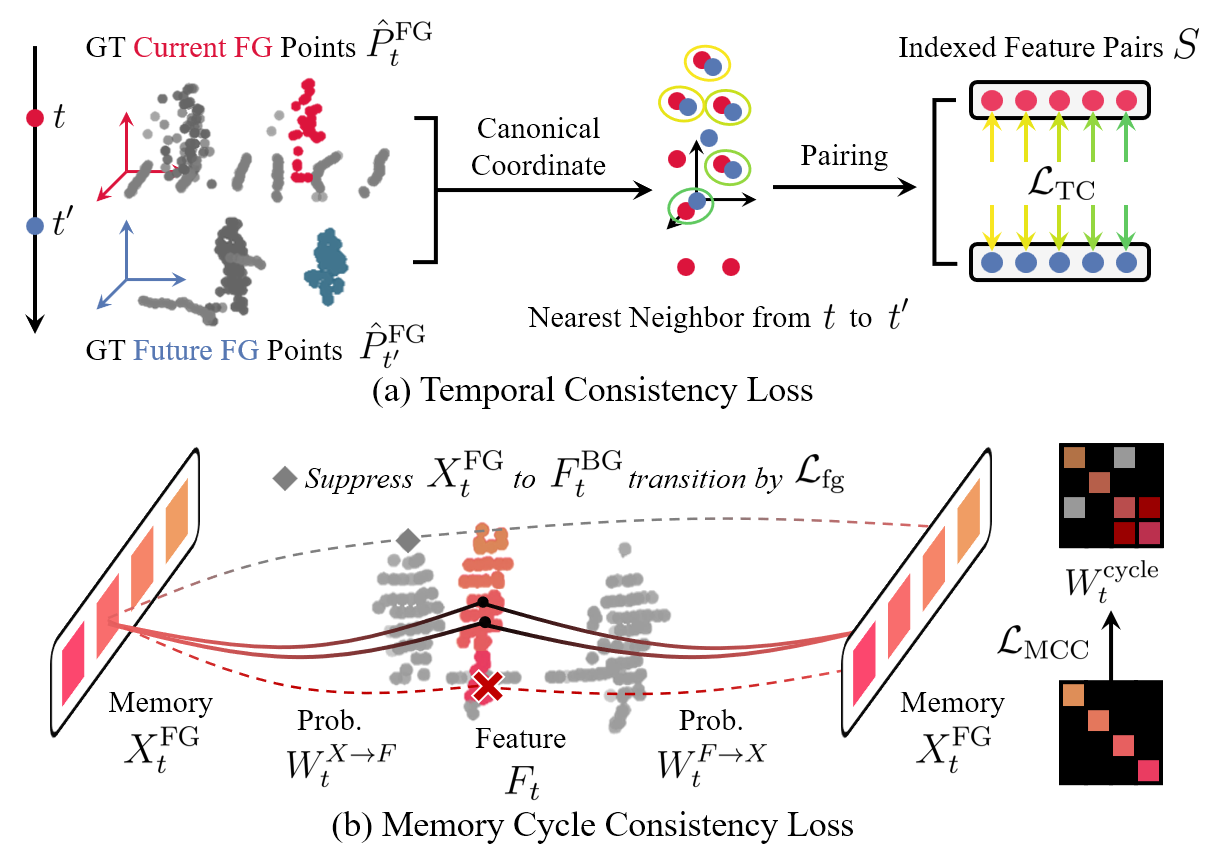
Temporally Consistent Long-Term Memory for 3D Single Object Tracking
Jaejoon Yoo, SuBeen Lee, Yerim Jeon, Miso Lee, and Jae-Pil Heo IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) Findings, 2026 code / paper / arXiv |
|
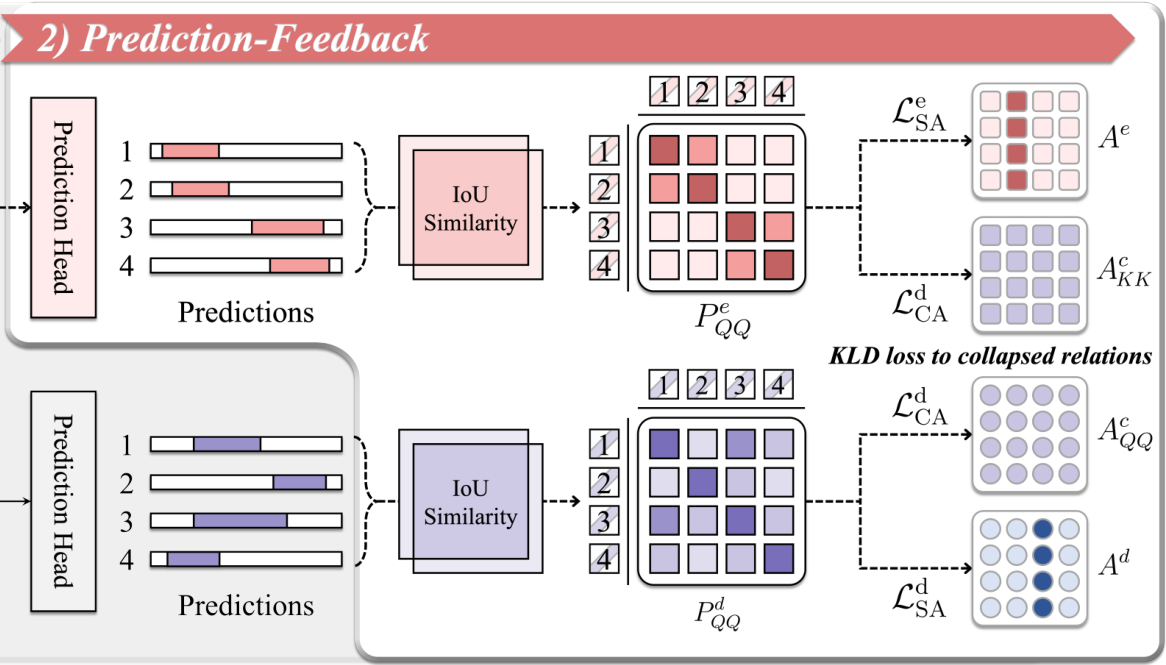
Prediction-Feedback DETR for Temporal Action Detection
Jihwan Kim, Miso Lee, Cheol-Ho Cho, Jihyun Lee, and Jae-Pil Heo AAAI Conference on Artificial Intelligence (AAAI), 2025 paper / arXiv |
|
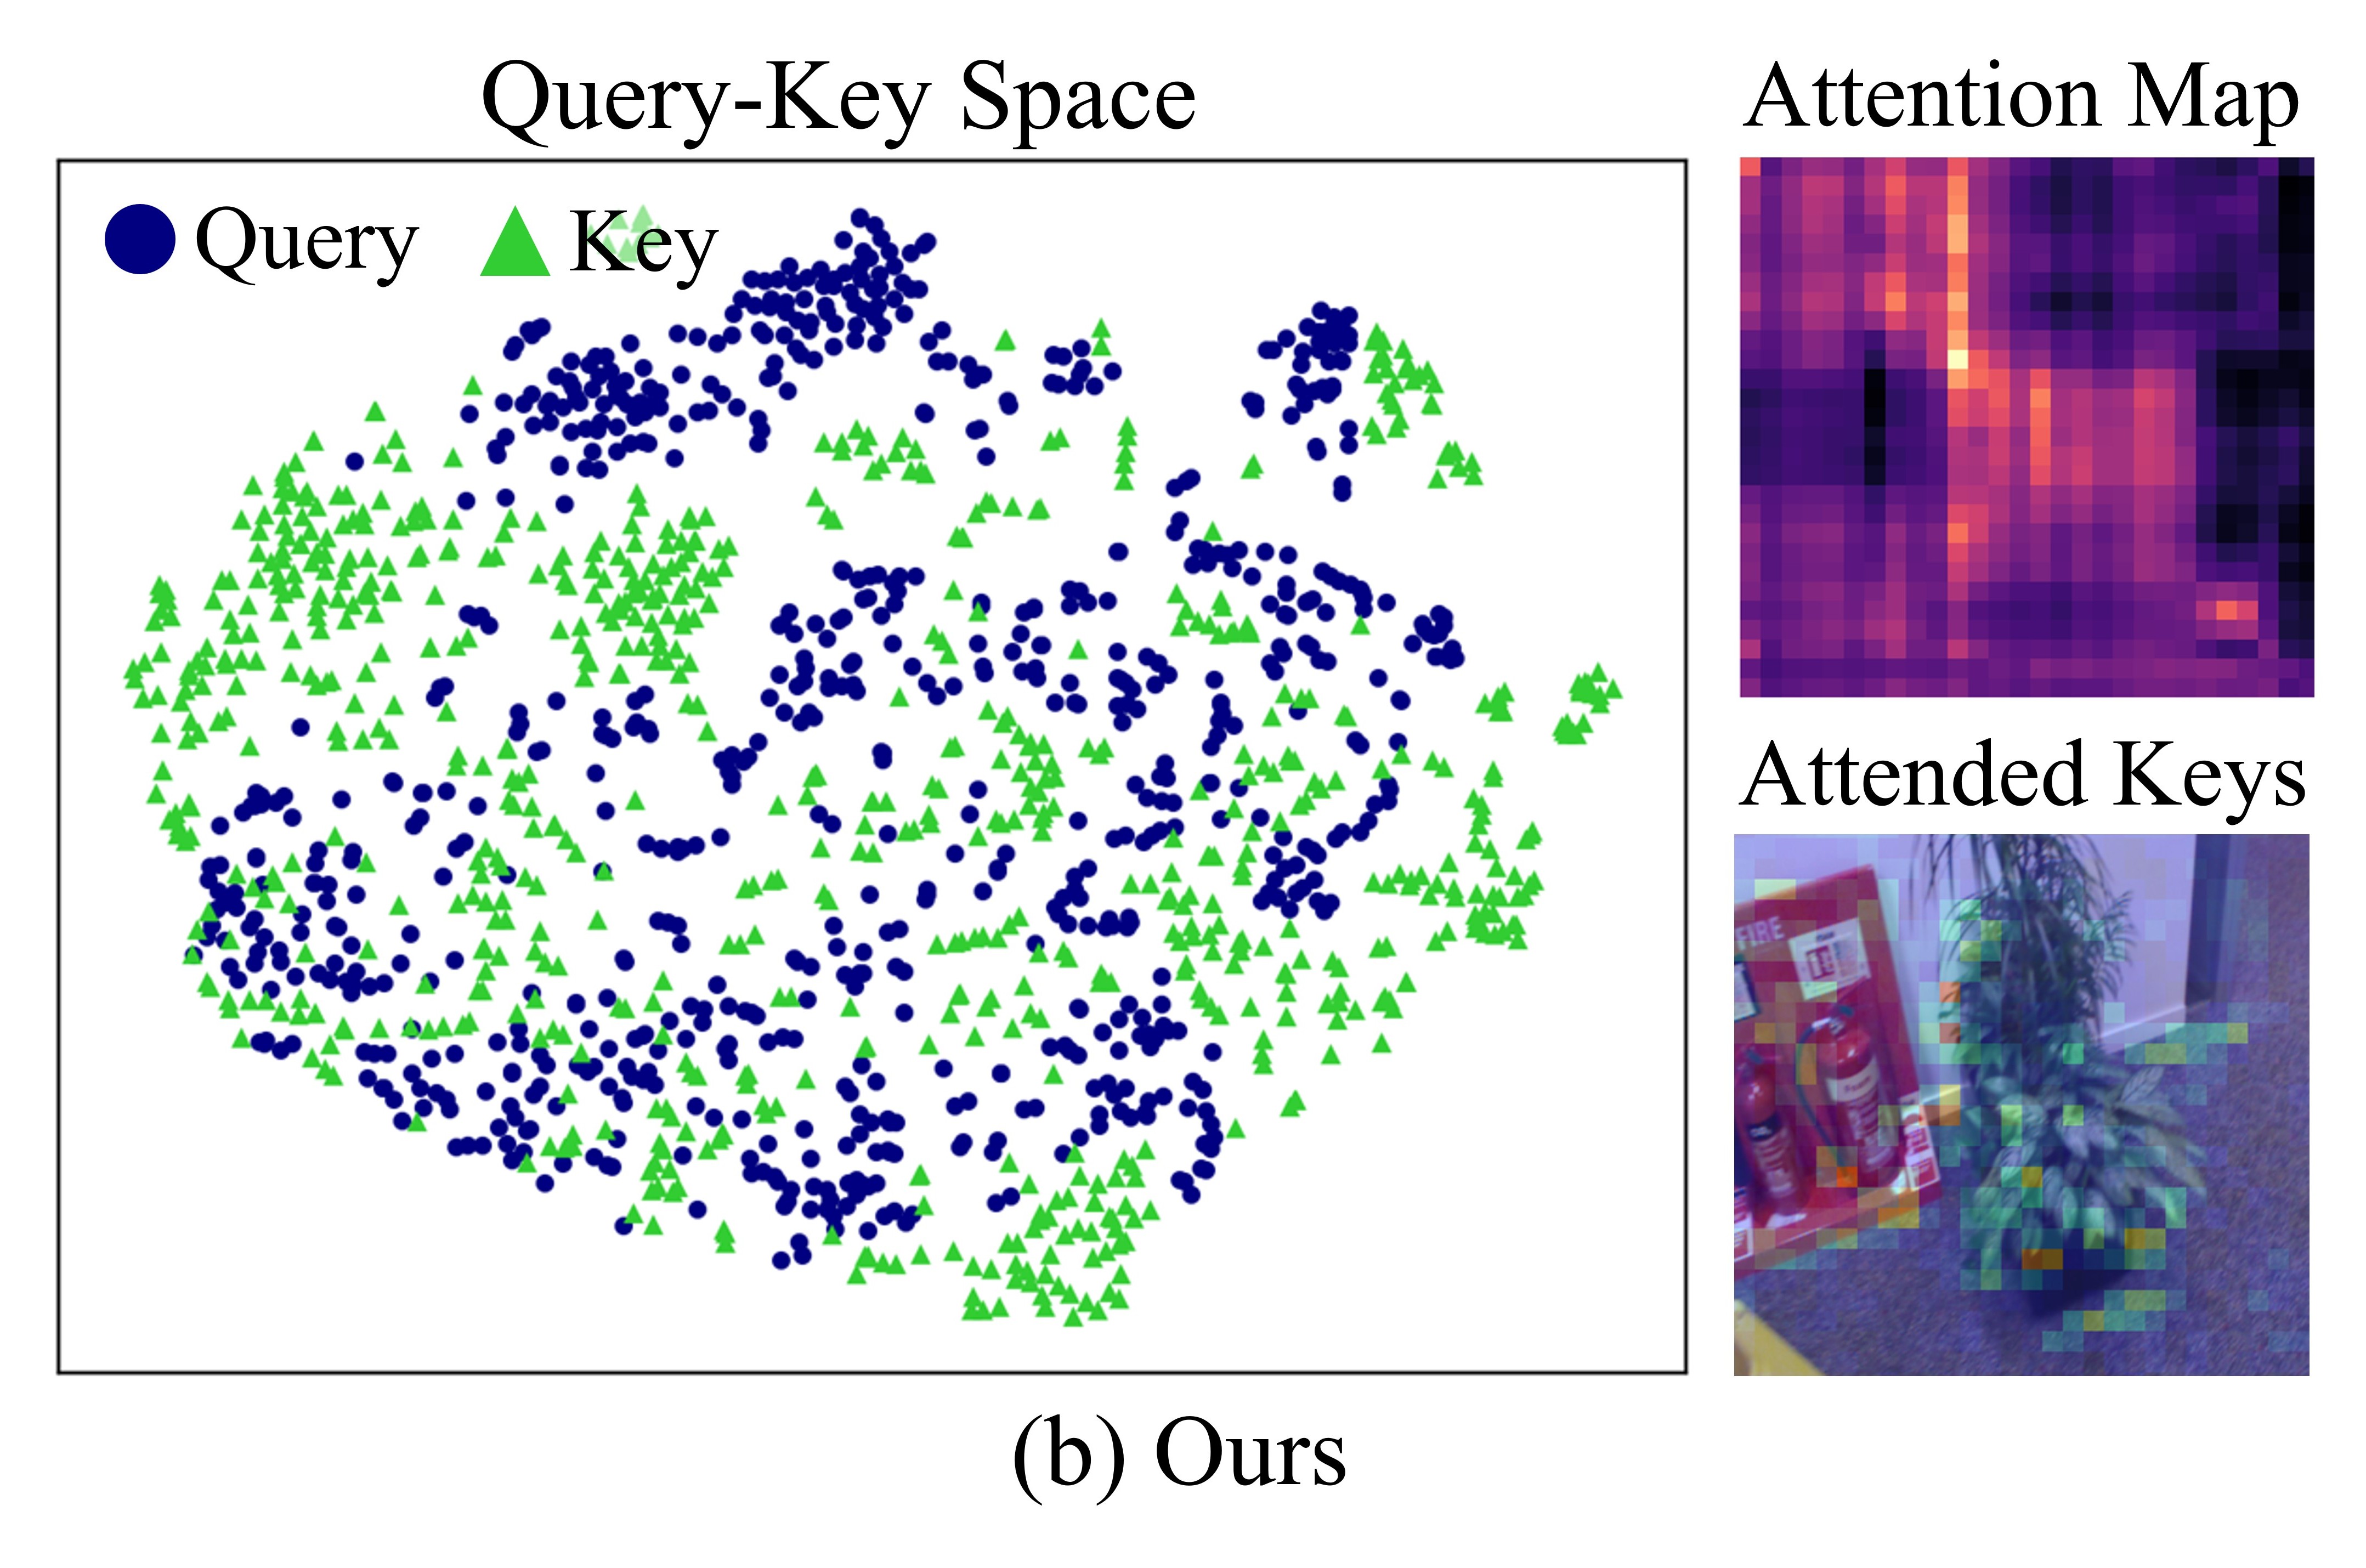
Activating Self-Attention for Multi-Scene Absolute Pose Regression
Miso Lee, Jihwan Kim, and Jae-Pil Heo Advances in Neural Information Processing Systems (NeurIPS), 2024 code / paper / arXiv |
|
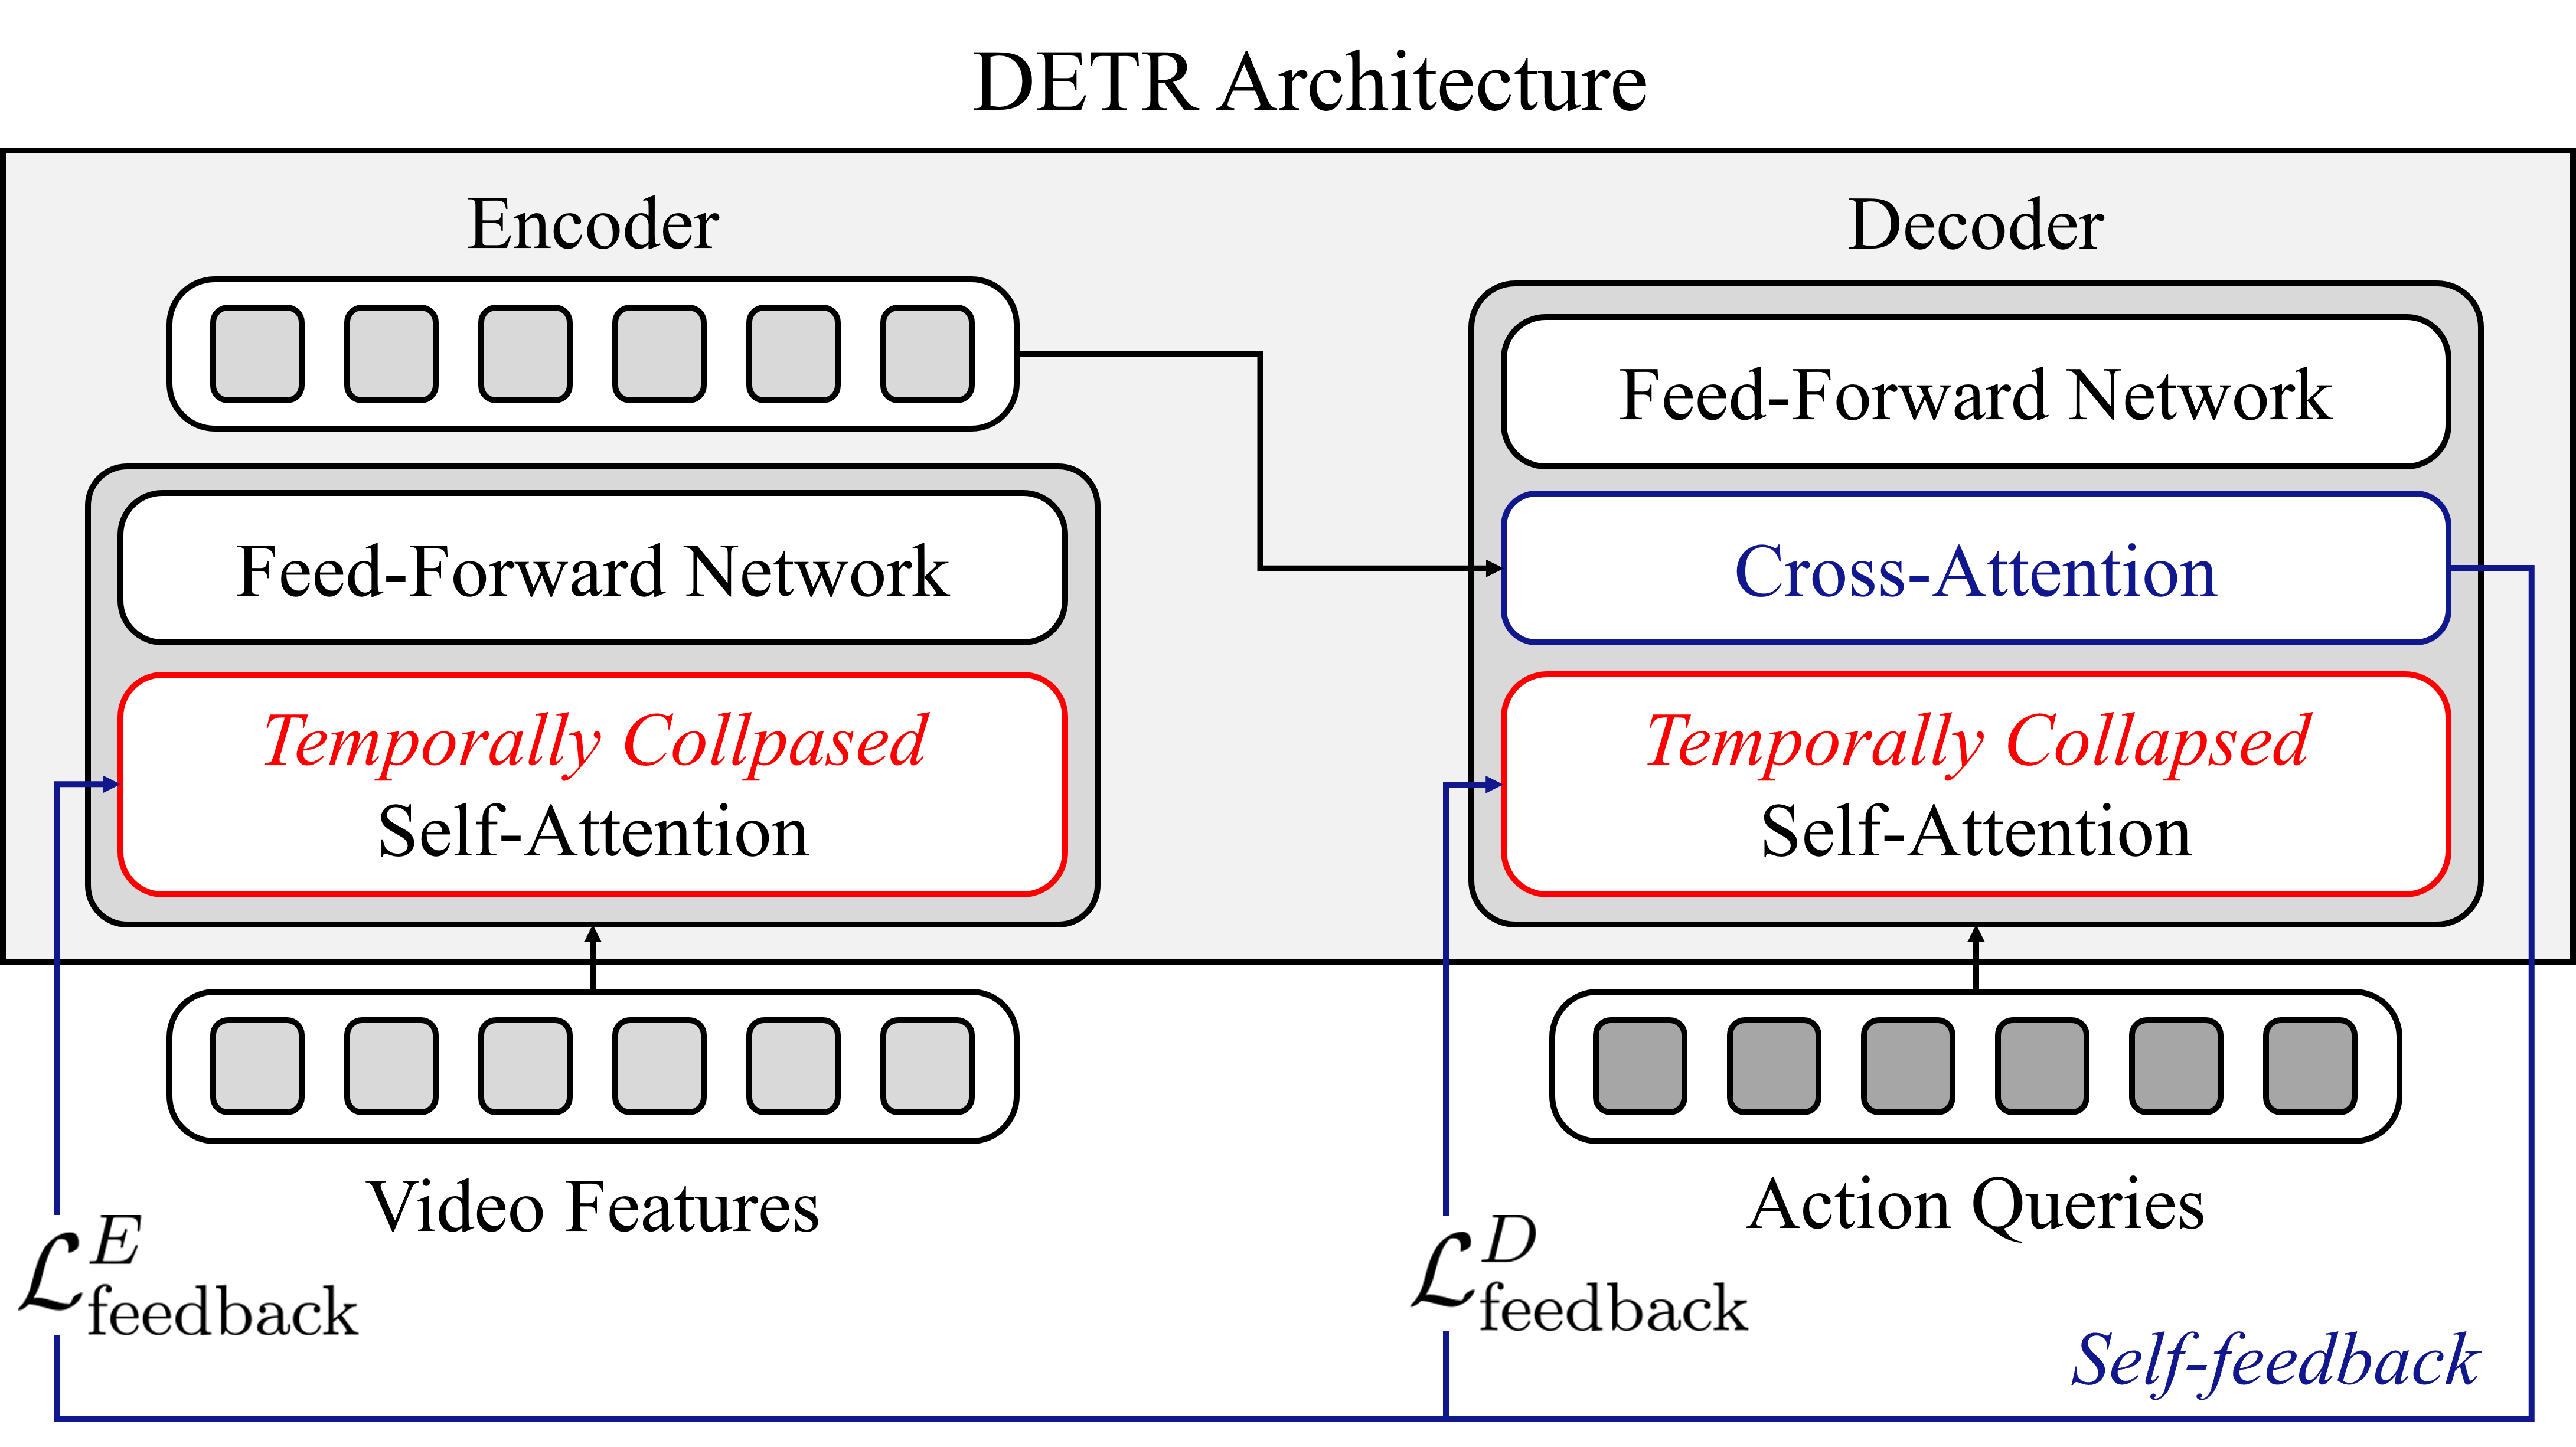
Self-Feedback DETR for Temporal Action Detection
Jihwan Kim, Miso Lee, and Jae-Pil Heo IEEE/CVF International Conference on Computer Vision (ICCV), 2023 paper / arXiv |
Preprints |
|
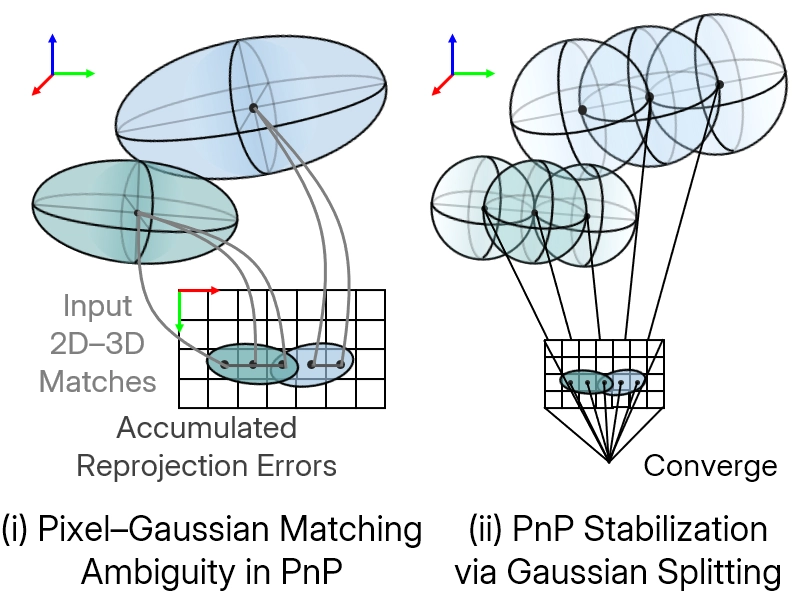
Disambiguating 2D-3D Correspondences for Visual Localization with Gaussian Splats
Miso Lee, Sangeek Hyun, Yerim Jeon, and Jae-Pil Heo arXiv |
|
|